












 Dan’s Biz Bookshelf: ‘Building a Story Brand 2.0’
 It’s Only Common Sense: Why Should They Take Your Call?






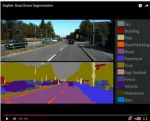
Two newly-developed systems for driverless cars can identify a user's location and orientation in places where GPS does not function, and identify the various components of a road scene in real time on a regular camera or smartphone, performing the same job as sensors costing tens of thousands of pounds.
The separate but complementary systems have been designed by researchers from the University of Cambridge and demonstrations are freely available online. Although the systems cannot currently control a driverless car, the ability to make a machine 'see' and accurately identify where it is and what it's looking at is a vital part of developing autonomous vehicles and robotics.
The first system, called SegNet, can take an image of a street scene it hasn't seen before and classify it, sorting objects into 12 different categories -- such as roads, street signs, pedestrians, buildings and cyclists - in real time. It can deal with light, shadow and night-time environments, and currently labels more than 90% of pixels correctly. Previous systems using expensive laser or radar based sensors have not been able to reach this level of accuracy while operating in real time.
Users can visit the SegNet website and upload an image or search for any city or town in the world, and the system will label all the components of the road scene. The system has been successfully tested on both city roads and motorways.
For the driverless cars currently in development, radar and base sensors are expensive - in fact, they often cost more than the car itself. In contrast with expensive sensors, which recognise objects through a mixture of radar and LIDAR (a remote sensing technology), SegNet learns by example -- it was 'trained' by an industrious group of Cambridge undergraduate students, who manually labelled every pixel in each of 5000 images, with each image taking about 30 minutes to complete. Once the labelling was finished, the researchers then took two days to 'train' the system before it was put into action.
"It's remarkably good at recognising things in an image, because it's had so much practice," said Alex Kendall, a PhD student in the Department of Engineering. "However, there are a million knobs that we can turn to fine-tune the system so that it keeps getting better."
SegNet was primarily trained in highway and urban environments, so it still has some learning to do for rural, snowy or desert environments -- although it has performed well in initial tests for these environments.
The system is not yet at the point where it can be used to control a car or truck, but it could be used as a warning system, similar to the anti-collision technologies currently available on some passenger cars.
"Vision is our most powerful sense and driverless cars will also need to see," said Professor Roberto Cipolla, who led the research. "But teaching a machine to see is far more difficult than it sounds."
Page 1 of 2


